Open to Forward Deployed Engineer & Data/AI platform roles

Sviat Nahirnyi — Forward Deployed Engineer, Data & AI Platforms. From the warehouse floor to production AI.

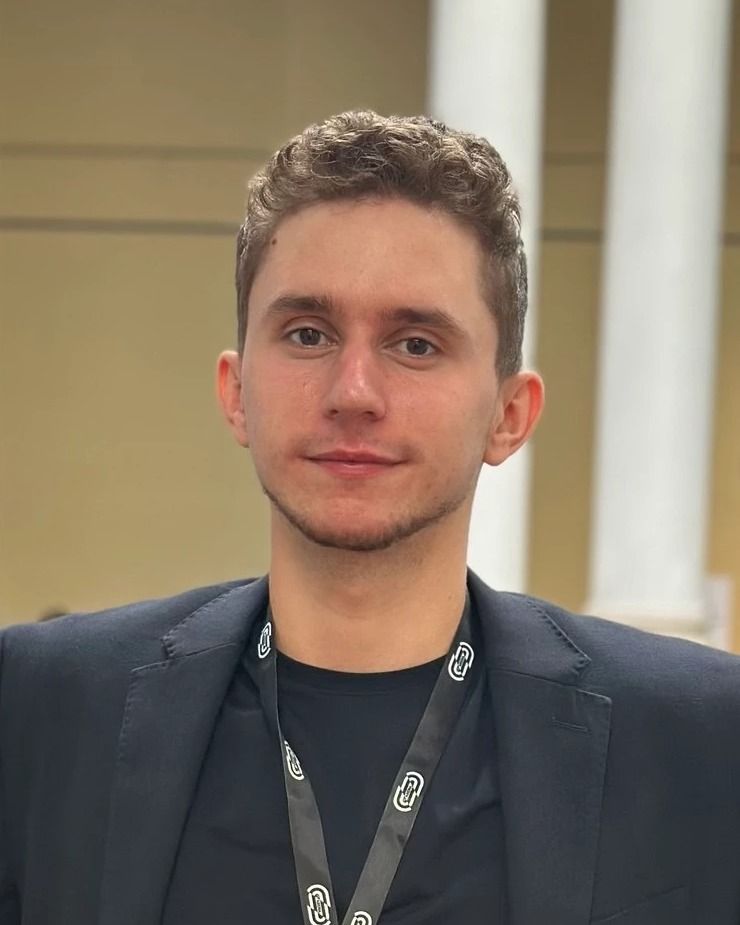
Portrait of Sviat Nahirnyi

I embed with the people who run operations — in warehouses, factories and client offices — map how the work really happens, and ship the Data & AI platforms they end up relying on: Lakehouses, real-time streaming, RAG and LLM evaluation.

Get in touchDownload CV PDFAsk my CV
  • Top-20European logistics co. — the largest deal I led at the company I co-founded
  • 9client engagements delivered by the practice I built
  • 1 monthPoC that won an aerospace data-platform tender
  • 6 yrsin data engineering · M.Sc. in AI

Selected clients & engagements

  • Dow Jones
  • Top-20 European logistics co.
  • Cisco (observability PoC)
  • Fortune 500
  • Aerospace (tender PoC)

01impact.metrics

Proof, not adjectives.

Six numbers from six years of shipping data platforms into real operations. Every one of them is on my CV and came from a production system, not a demo.

  • 0→17

    Graphit

    engineers in the Data & AI practice

    Built from zero across 9 client engagements — real-time platforms, Lakehouse migrations, LLM evaluation systems.

  • −30%

    Graphit

    flagged chatbot responses

    Architected an LLM-as-a-Judge evaluation platform for production chatbot responses.

  • 39→1

    Sigma Software

    sources into one Lakehouse

    Source-of-truth platform for an international logistics company, serving 5 analytics & ML teams.

  • +6%

    Graphit

    operational performance

    Embedded on-site in a top-20 European logistics company’s warehouses, then shipped the analytics platform.

  • −37%

    Sigma Software

    end-to-end pipeline runtime

    Built incremental PySpark pipelines on Databricks.

  • 50K+/s

    SoftServe

    events per second, real time

    Spark Structured Streaming for telecom network-map visualisation and latency detection.

02deployment.log

Six years, two tracks, one job: make data useful.

I co-founded Graphit in 2023 and ran its Data & AI practice while staying hands-on in client delivery — so from 2023 the tracks run in parallel.

From March 2023 the tracks run in parallel: co-founding Graphit while staying hands-on in client delivery. Select a bar to jump to the full role. Founder track: Co-Founder & Lead, Data & AI Platforms at Graphit, Mar 2023 – Aug 2026. Delivery track, in order: Data Engineer at N-iX, Oct 2020 – Sep 2021; Big Data Developer at SoftServe, Sep 2021 – Sep 2022; Data Engineer at Netminds, Sep 2022 – May 2023; Presales Software Engineer at GreenM, May 2023 – Aug 2023; Senior Data Engineer at Sigma Software, Jul 2023 – Jan 2025. GreenM and Sigma Software overlapped in summer 2023. Every role is detailed in the list below.
  1. Jul 2023 – Jan 2025Münster, Germany

    Senior Data Engineer · Sigma Software Group

    • Delivered the source-of-truth Lakehouse for an international logistics company — 39 operational sources consolidated into one platform serving 5 analytics and ML teams — by embedding on-site at the client’s factory to design ETL flows with operations staff.
    • Designed analytical dashboards for factory and logistics stakeholders on-site, mapping shop-floor workflows directly into data models and reporting.
    • Reduced end-to-end pipeline runtime by 37% by building incremental PySpark pipelines on Databricks.
    • Databricks
    • PySpark
    • Lakehouse
    • ETL
    • Dashboards
  2. May 2023 – Aug 2023Hybrid, US

    Presales Software Engineer · GreenM

    • Won a data-platform tender for an aerospace company via a one-month PoC delivered directly with the client’s stakeholders, validating ingestion, storage, and query latency on terabytes/day.
    • Enabled unified alerting across 7 networking-metric sources by building the Kubernetes-native ingestion layer for a Cisco observability PoC.
    • Kubernetes
    • PoC delivery
    • Observability
    • TB/day ingestion
Earlier roles · 2020–23Data Engineer · Netminds · Sep 2022 – May 2023Big Data Developer · SoftServe · Sep 2021 – Sep 2022Data Engineer · N-iX · Oct 2020 – Sep 2021
  1. Sep 2022 – May 2023Remote

    Data Engineer · Netminds

    • Halved new-pipeline delivery time (4 days → 2) by rebuilding the platform around reusable ingestion templates.
    • Lifted loyalty engagement 10% with Spark / Scala pipelines feeding an AI-driven offers engine.
    • Shortened release cycles from 3 days to 1 by establishing Azure DevOps CI/CD for Databricks.
    • Spark
    • Scala
    • Databricks
    • Azure DevOps
  2. Sep 2021 – Sep 2022Remote

    Big Data Developer · SoftServe

    • Built a Spark Structured Streaming system handling 50K+ events/second for real-time telecom network-map visualisation and latency detection.
    • Translated ambiguous stakeholder requirements into service boundaries, SLAs, and data contracts; built demos used in design reviews that helped upsell the account.
    • Spark Structured Streaming
    • Real-time
    • Data contracts
    • SLAs
  3. Oct 2020 – Sep 2021Remote

    Data Engineer · N-iX

    • Secured sensitive datasets for a Fortune 500 company with a permissioned AWS data warehouse — Airflow, RBAC, Terraform CI/CD — plus a data-quality framework of 100+ automated checks.
    • AWS
    • Airflow
    • Terraform
    • RBAC
    • Data quality

Education M.Sc. & B.Sc. in Artificial Intelligence — Lviv Polytechnic National University

03case.studies

Two of many deployments, up close.

Six years of client delivery, nine engagements at Graphit alone. Here are two of my most recent projects, end to end: an AI system and a data platform — each with its live pipeline.

Case 01 · AI · Graphit

Cutting flagged chatbot responses by 30%.

I architected an LLM-as-a-Judge evaluation platform that checks a chatbot’s answers twice: live, before a user sees them, and offline, before every release. Flagged responses fell by 30%.

Read the full case study: Cutting flagged chatbot responses by 30%.

case 01 · chatbot_answers → judged_answers

demopausedstatic frame · reduced motionsimulated≈ 1,840 answers/minflag rate ≈ 10%−30% flagged

Animated diagram of the LLM-as-a-Judge case: a chatbot answers user questions; a judge model scores every answer before it is served, blocks or reroutes low scores, and sends failures to an evaluation set whose regression tests gate every release. Simulated demo.

  1. the bot’s sourcesChatbot side — simplified to a RAG bot for this demo
    • docs
    • tickets
    • chats
    • users
  2. chunk · vectoriseChatbot side — simplified for this demo
  3. vector index · top-kChatbot side — simplified for this demo
  4. LLM · answerChatbot side — simplified for this demo
  5. live gate · every answerLive: every answer scored before users see it — low scores blocked or rerouted
    • users
  • document chunk
  • query
  • retrieved context
  • answer
  • flagged by judge

Hover or focus a stage for detailsTap a stage for details

A live demo of the pipeline, rewired for this case. The chatbot side is simplified and the judge’s criteria are illustrative; the judge, the eval set and the release loop are what I built. Rates are simulated — the −30% is the real result.

04how.i.work

Forward deployed, end to end.

The job isn’t just writing pipelines. It’s earning trust on-site, finding the real problem, shipping something that runs in production — and proving it worked.

  1. Embed

    Sit with the operators where the work happens — not in a requirements meeting.

    • Warehouses, a factory floor and Dow Jones’ Barcelona office
  2. Map

    Turn tribal knowledge into data models, contracts and SLAs that engineers can build against.

    • Shop-floor workflows → data models, contracts & SLAs
  3. Ship

    Build the platform in production — streaming, Lakehouse, retrieval — not in slides.

    • Lakehouse, streaming and retrieval in production
  4. Prove

    Measure it: evaluation gates, data-quality checks and the business KPI that moved.

    • LLM-as-a-Judge evals · 100+ data-quality checks
  5. Scale

    Turn one success into the next deal — and the team to deliver it.

    • Largest enterprise deal · a tender won with a PoC
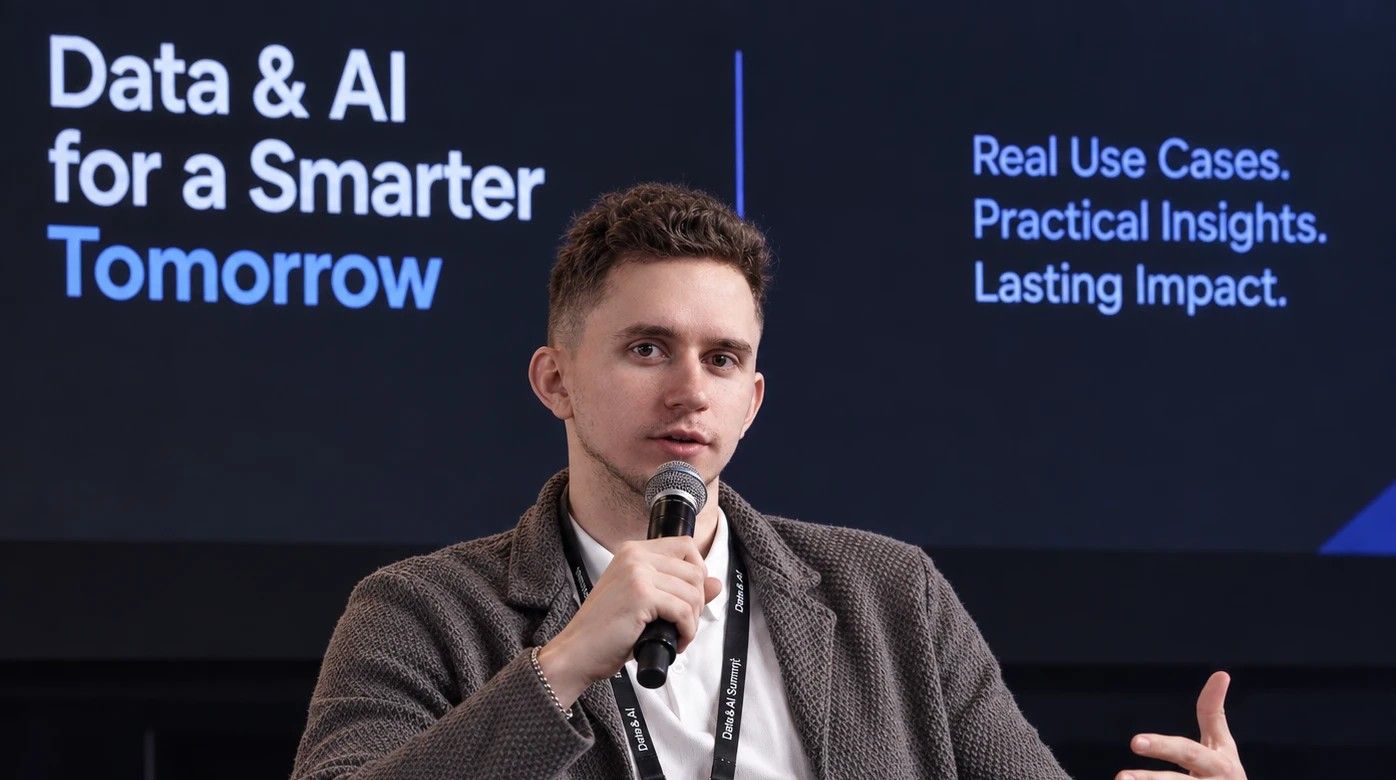
Sviat Nahirnyi speaking with a microphone on a panel at the Data & AI Summit

fig. field_note

Same job on a panel as on a warehouse floor: make Data & AI useful to the people who have to live with it.

Panelist · Data & AI Summit

05rag.playground

Ask my CV. Watch the retrieval.

It runs 100% in your browser — hybrid retrieval over 44 chunks of my CV, then an eval gate decides whether the answer is allowed out — a small, rule-based take on the LLM-as-a-Judge idea behind my −30% flagged-responses result.

ask_cv · console

44 chunks · 384-d int8 · 49 KB

Try

~29 MB · opt-in

Off · BM25 keyword retrieval, instant. Suggested questions already use precomputed embeddings. On downloads ~23 MB model + ~6 MB runtime, once.

Answer · extractive

idle

Pick a question above or type your own. The answer is stitched together from CV sentences only — then the judge decides whether it may be shown.

fast · BM25 · k=4

Embedding map · 2D PCA

44 chunks

  • AI / LLM12
  • Data & Streaming9
  • Forward Deployed11
  • Cloud & DevOps4
  • Leadership2
  • Profile6

MiniLM vectors projected to 2D; the query lands near what it retrieves. A sketch — 2D keeps ~20% of the variance, retrieval uses all 384 dimensions.

Eval gate · judge

idle

5 checks · awaiting a question

  • Retrieval relevance—awaiting a question
  • Groundedness—awaiting a question
  • Citation coverage—awaiting a question
  • Scope—awaiting a question
  • Privacy policy—awaiting a question
50 · balanced

relevance ≥ 0.35 · grounded ≥ 70% · coverage ≥ 60%

Retrieved chunks · top-4

k=4 of 44

  1. Nothing retrieved yet.
how_it_worksWhat runs where — and what’s real
  1. query
  2. tokenise
  3. BM25 + MiniLM 384-d cosine
  4. top-k (k=4)
  5. extractive answer
  6. judge
  7. verdict
Index offline · Node
44 chunks generated from the same data as this page → all-MiniLM-L6-v2 (quantised, mean-pooled, normalised) → 384-d vectors stored as int8, plus a 2D PCA basis. Ships as a 49 KB JSON that loads only when you scroll here.
Fast mode your browser
BM25 (k1 1.2, b 0.75) with stopwords, light stemming and a small domain synonym map — llm → judge, rag, evaluation; cloud → aws, azure, terraform. Instant; no model.
Suggested questions your browser
Their embeddings were computed at build time, so they get true hybrid retrieval (normalised BM25 + cosine) without downloading anything.
Semantic mode your browser · Web Worker
Only when you switch it on: transformers.js and the same MiniLM model (~23 MB + ~6 MB runtime, cached afterwards). Your question is embedded locally and compared by brute-force cosine with all 44 chunks — right at this size; at production scale that becomes an ANN index such as HNSW.
Answer extractive
The 2–3 best sentences from the top-4 chunks, ranked by query-term overlap × chunk score, each with a citation. No generated text, so nothing to hallucinate.
Judge rule-based
A deterministic stand-in for an LLM-as-a-Judge with the same gate: relevance, groundedness, citation coverage, scope and a privacy policy. Extractive answers are grounded by construction — the check is there so a generative model could never slip an unsupported claim past it.
Map decorative
2D PCA keeps ~20% of the variance, so treat it as a sketch. Typed questions without an embedding are placed at the score-weighted centroid of their top-4.
Privacy by design
Nothing you type leaves this tab — there is no server and no LLM API behind this console.

06side.projects

Side projects, shipped.

What I build outside client work: products where AI does one useful job — analysing conversations, parsing messy documents, or extracting structure. One of them grew into a Graphit platform.

  • AI analytics · Side project → Graphit platform

    ConvoInsights

    See where your chatbot fails — in every conversation.

    Analyses every AI-chatbot conversation to surface drop-offs, failure flows and frustrated users — topics, sentiment and recommendations that help development and CX teams cut escalations.

    Started as a side project; it later became one of Graphit’s key platforms for its customers.

    • Conversation analytics
    • LLM classification
    • Sentiment
    • Dashboards
  • iOS app · AI

    Fortium (opens in a new tab)

    The program you already follow. Now it runs itself.

    A strength-training log that turns a coach’s PDF, a spreadsheet or a photo of a notebook into a working program — with progressive-overload targets on every set, PR detection and an AI coach that proposes changes for your approval.

    • Document → structured data
    • LLM parsing
    • iOS
  • App · AI

    Actium (opens in a new tab)

    Turn self-help books into daily quests.

    AI that extracts the lessons from a book and turns them into personalised daily actions — with streaks, points and progress across Body, Mind, Soul and Spirit.

    • LLM extraction
    • Personalisation
    • Gamification
  • Open source · MCP

    Hilka (opens in a new tab)

    Log how you think, not just what you decided.

    A decision-tree journal that keeps the branches you rejected. Ships an MCP server and a Claude Code plugin so AI assistants can write decision trees straight into your account.

    • React 19
    • Supabase / Postgres
    • Cloudflare Workers
    • MCP
    source on GitHub (opens in a new tab)

07stack.lock

Tools I reach for.

No skill bars — the tools I work with, most of them on client projects.

01 The part that doesn’t fit on a tech list.

Forward Deployed

  • On-site solution design
  • Enterprise PoCs
  • Requirements → data contracts
  • Presales

02 Retrieval, evaluation and agentic systems.

AI / LLM

  • HuggingFace
  • LangChain
  • LLM-as-a-Judge evaluation
  • Vector retrieval
  • RAG
  • MLflow
  • Agentic systems

03 The platforms everything else stands on.

Data & Streaming

  • SQL
  • Spark
  • Streaming
  • Databricks
  • Airflow
  • Kafka
  • Python
  • Scala
  • Flink
  • Snowflake

04 Shipped, versioned, repeatable.

Cloud & DevOps

  • AWS (SageMaker, Bedrock, Glue, EKS, S3)
  • Azure (ADF, Synapse)
  • MLOps
  • Kubernetes
  • Terraform

08deploy

Got messy operational data and an AI ambition?

I’m looking for my next Forward Deployed Engineer or Data & AI platform role — somewhere I can sit with customers, find the real problem and ship the thing that fixes it. London-based, happy to travel on-site.

  • Available now · London, UK
  • UK right to work — no sponsorship needed
  • Hybrid · on-site · remote · relocation

↑↓ navigate↵ selectesc close> terminal

↵ run↑ historytab complete⌫ back

Type > for the terminal